
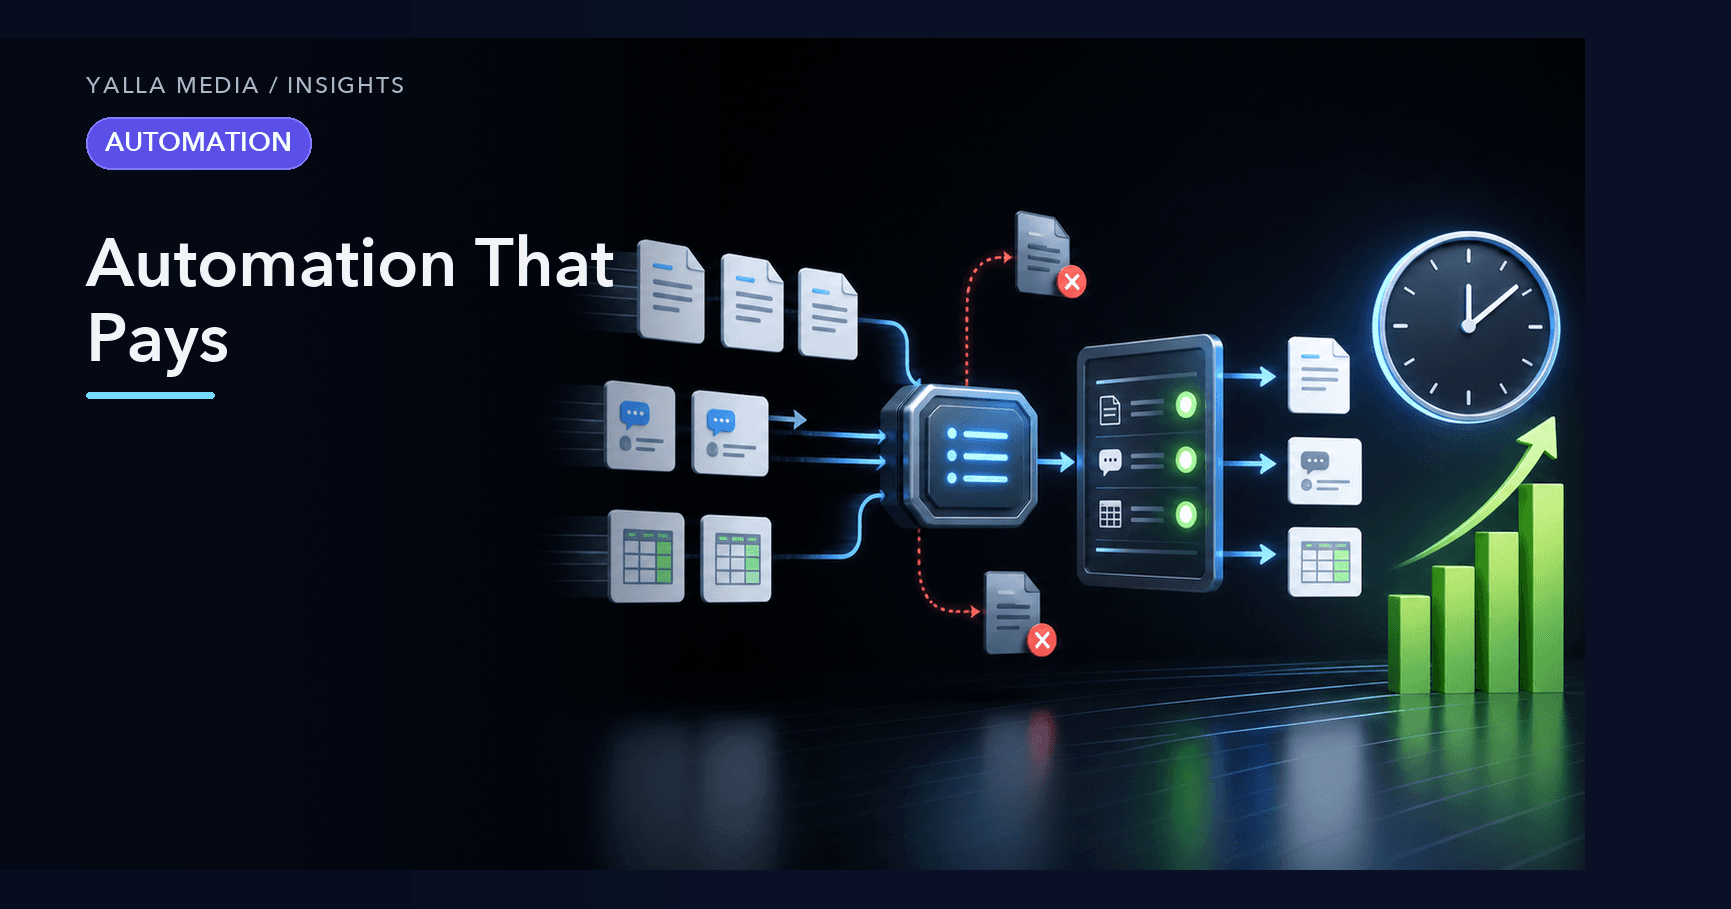
Automation is sold as free time and delivered, too often, as a new category of problem. A workflow that fails silently, runs twice, or breaks in a way nobody notices does not save effort — it relocates it, usually to a worse moment. The difference between automation that pays for itself and automation that quietly costs you comes down to three things: aiming it at the right work, building it to be reliable, and making it visible.
Get those right and automation does exactly what it promises. Even reclaiming a few hours a week of repetitive work, reliably, compounds into real capacity. The trick is that reliability and visibility are not optional polish — they are the difference between a tool you trust and a tool you have to babysit.
Choose what to automate first
The instinct is to automate the most annoying task. The better instinct is to automate the task with the best ratio of frequency and stability to effort. Annoying-but-rare is a poor candidate; frequent-and-stable is gold.
The shortlist criteria
- It happens often. Frequency is what turns a one-time build into ongoing savings. Automating something that runs once a quarter rarely pays back.
- It is rule-based. Work with clear, stable rules automates cleanly. Work that requires judgment every time does not — at least not fully.
- It is well-defined. If you cannot describe the steps precisely, you cannot automate them reliably. Fuzzy processes produce fuzzy automation.
- The cost of a mistake is bounded. Start where an error is recoverable, not where a single bad run causes lasting damage.
Begin with the unglamorous, high-frequency, rule-based tasks — the routine refreshes, the repetitive transformations, the predictable hand-offs. They are the safest place to learn and the fastest place to see return.
Build it idempotent
The most important property of a reliable workflow is idempotency: running it more than once produces the same result as running it once. This sounds academic until the first time a job retries, a trigger double-fires, or someone runs it twice by mistake — and you discover the difference between a workflow that shrugs and one that creates duplicates, double-charges, or corrupts state.
Assume every step will, eventually, run twice. Design so that the second run is harmless. That single assumption prevents most of the worst automation failures.
How to make a workflow idempotent
- Use stable identifiers. Key each unit of work to a unique, deterministic identifier so a repeat run recognizes what it has already done.
- Check before you act. Before creating, sending, or charging, check whether it already happened. Make the operation a no-op if it did.
- Prefer upserts to blind inserts. Operations that set a known end-state are safer to repeat than operations that blindly add.
- Make retries safe by default. Failures are normal; the system should be able to retry without fear, because that is what robust systems do automatically.
Idempotency is what lets you trust automation enough to stop watching it. Without it, every retry is a gamble and you never fully relax.
Make it observable
A workflow you cannot see is a workflow you cannot trust. Observability is the difference between knowing your automation is working and merely hoping it is. The goal is that when something goes wrong, you find out quickly, with enough context to fix it — instead of discovering it days later through its downstream damage.
The minimum worth building
- Logs with context. Record what ran, when, on what, and what happened — enough to reconstruct a run after the fact.
- Alerts on failure. A failure nobody is told about is a failure that festers. Surface problems actively; do not wait to stumble on them.
- A clear status view. Someone should be able to answer "is it working?" at a glance, without spelunking.
- Meaningful failures. When something breaks, the signal should point at the cause, not just announce that something, somewhere, went wrong.
Observability changes the relationship with automation from anxious to confident. You stop checking obsessively because the system tells you when it needs you — and only then.
Keep a human in the loop where it matters
Not everything should run untouched. For high-stakes steps, a human checkpoint is a feature, not a failure of automation. The art is automating the repetitive ninety percent while keeping judgment in the loop for the consequential ten — letting the workflow do the gathering and preparing, and letting a person make the call that actually matters.
The payback test
Before you build, and after, ask the honest question: does this save more than it costs, including the cost of maintaining it? Automation that is reliable, observable, and pointed at frequent rule-based work passes easily and keeps paying. Automation that is fragile, invisible, and aimed at the wrong task fails the test no matter how clever it looked on day one. Choose well, build it to run twice safely, and make it impossible to ignore when it breaks. That is automation that pays for itself.