
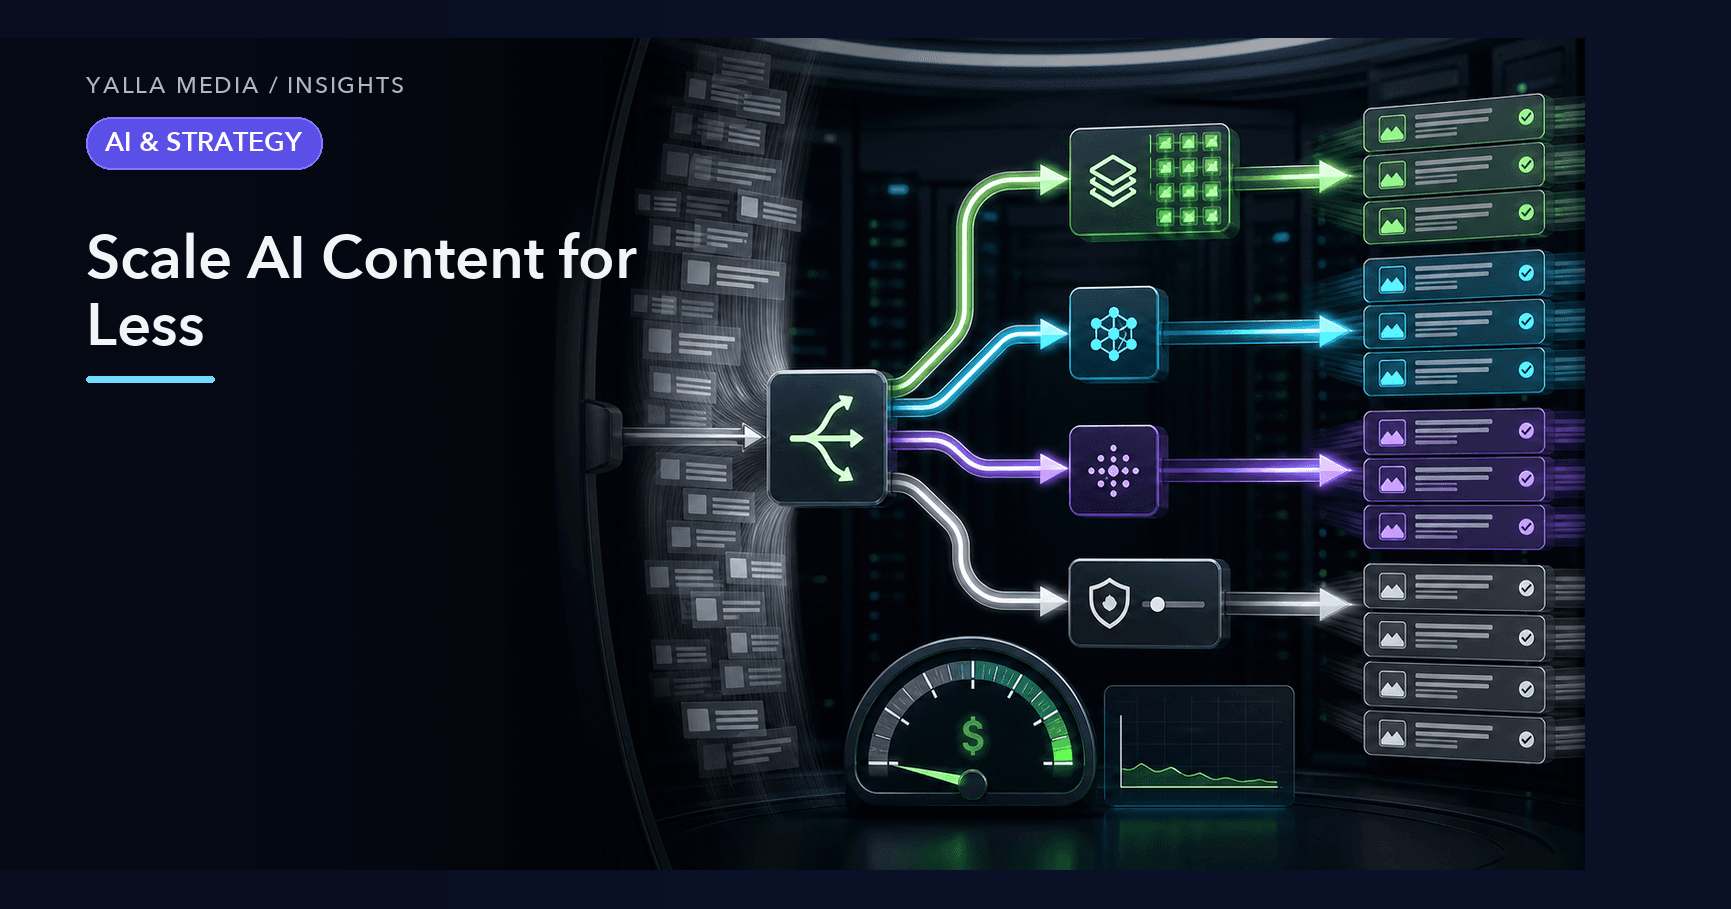
The fear that kills AI ambition is the runaway bill. A team flips on generation, output climbs, and so does an invoice nobody scoped. The instinct is then to throttle usage — which throttles the value. There is a better path, and it is an architecture decision rather than a discipline one. Cost control should be built into how requests are routed and stored, not enforced by asking people to use the system less.
The goal is simple to state and very achievable: non-paying, everyday use should cost you close to nothing, while paid use comfortably covers the premium that paying customers actually consume. Get the plumbing right and you can scale output without scaling spend.
Route free-first, reserve premium for paid
Not every request needs the most capable, most expensive engine. A great deal of useful work — drafts, rewrites, summaries, classifications — runs perfectly well on free-tier or low-cost engines. The strategy is to default to the cheapest engine that does the job, and only escalate when the task genuinely demands it.
A tiered routing policy
- Free and low-cost engines by default. Route ordinary requests here, especially anything triggered by non-paying accounts.
- Premium engines reserved for paid plans. The capability that costs real money is gated behind the payment that covers it.
- Escalate by task, not by habit. Reach for the expensive engine only when the task is high-stakes or genuinely beyond the cheaper tier — not because it is the default in someone's muscle memory.
The principle underneath: payment should track cost. If a customer is paying, they unlock the engines that cost you more. If they are not, they get capable free-tier output that costs you near zero to provide.
Cache aggressively — the cheapest request is the one you never make
Generation you already paid for should never be paid for twice. Caching is the highest-leverage cost lever there is, because a cache hit is effectively free. Identical or near-identical requests should be served from a stored result rather than re-run.
The cheapest token is the one you never spend. Before optimizing which engine answers a request, ask whether the request needs to reach an engine at all.
Design caching deliberately:
- Cache by normalized input. Strip trivial differences so that functionally identical requests collapse to the same cache key.
- Serve repeats at zero cost. An identical re-run should cost the user nothing and cost you nothing — it is a lookup, not a generation.
- Set sensible lifetimes. Some outputs are evergreen and can be cached for a long time; others should expire. Match the lifetime to how fast the underlying answer goes stale.
For high-traffic, repetitive tools, caching alone can absorb a large share of demand. The popular requests get answered once and served many times.
Make credits the unit of restraint
Credits turn an abstract cost into a concrete, visible budget — for you and for the user. Each run costs a small, known number of credits; each account gets an allowance. This does three things at once: it bounds usage automatically, it makes the value exchange legible, and it gives you a clean lever for tiering plans.
- Free accounts get a monthly allowance generous enough to be genuinely useful, bounded enough to be safe.
- Cache hits cost zero credits. Reward repetition rather than punishing it.
- Paid plans get larger allowances and premium engines — the upgrade path is built into the same mechanic.
Because credits are denominated in your real costs, the system self-regulates. Heavy users either fit inside a generous allowance or move to a plan whose payment covers their consumption.
Put a hard ceiling on spend
Routing, caching, and credits handle the normal case. Spend caps handle the abnormal one — the runaway loop, the abuse spike, the unexpected surge. A global spend cap is the circuit breaker that guarantees a bad day cannot become a bad month.
Layer the caps
- Per-account limits stop any single user from consuming far beyond their share.
- A global ceiling on free-tier spend ensures total non-paying cost stays inside a number you chose on purpose.
- Graceful degradation when a cap is reached — slow down, queue, or fall back to cache rather than failing loudly or, worse, billing silently.
The architecture is the strategy
Put these four layers together — free-first routing, aggressive caching, credit budgets, and hard spend caps — and cost stops being a thing you worry about and becomes a property of the system. You can let people use the tools freely because the architecture guarantees the economics. That is the whole point: scale the value, not the bill.